
Graph Learning on Ensembles of Cyclic Peptides: An Investigation of Molecular Ensemble Modeling
0upvotes
By: Aaron Feller, Kris Deibler, Maxim Secor
Molecular property prediction from structure often uses a single representative conformation, even though many molecules exist as conformational ensembles in solution. We introduce EnsembleEGNN, a molecular ensemble foundation model that encodes an ensemble by first encoding each conformer with shared Equivariant Graph Neural Network (EGNN) layers, then pooling the resulting conformer representations with a Set Attention Block. We pretrain th... more
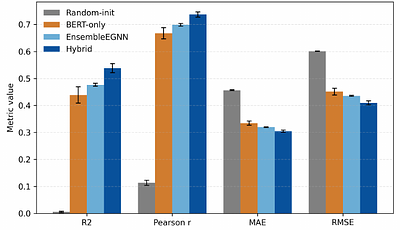
Molecular property prediction from structure often uses a single representative conformation, even though many molecules exist as conformational ensembles in solution. We introduce EnsembleEGNN, a molecular ensemble foundation model that encodes an ensemble by first encoding each conformer with shared Equivariant Graph Neural Network (EGNN) layers, then pooling the resulting conformer representations with a Set Attention Block. We pretrain the model on CREMP, a cyclic peptide ensemble dataset, using a multi-task self-supervised objective combining masked token recovery, noisy-coordinate reconstruction, and pairwise distance reconstruction. On the CREMP-CycPeptMPDB dataset, training EnsembleEGNN from scratch fails entirely ($R^2=0.005$). However, the pretrained model reaches $R^2=0.477$ and Pearson $r=0.699$, outperforming the sequence-only BERT baseline ($R^2=0.439$, Pearson $r=0.667$). When EnsembleEGNN is co-trained end-to-end with the BERT sequence encoder, the hybrid model improves further to $R^2=0.538$ and Pearson $r=0.737$. These results demonstrate that encoding conformational ensembles into a single thermodynamically informed embedding improves cyclic-peptide property prediction. less
Zero-Flow Two-Sample Tests
0upvotes
By: Yakun Wang, Leyang Wang, Song Liu, Taiji Suzuki
We propose a new approach to two-sample testing for deciding whether two sets of samples are drawn from the same distribution. The test is built on a statistical discrepancy based on the zero-flow criterion, termed zero-flow discrepancy (ZFD). We prove the validity of ZFD and propose a practical testing procedure, termed the zero-flow two-sample test (ZF2ST). The key idea is to learn how samples from the two distributions are locally misalign... more
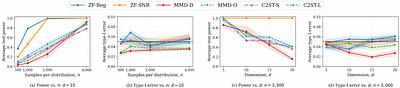
We propose a new approach to two-sample testing for deciding whether two sets of samples are drawn from the same distribution. The test is built on a statistical discrepancy based on the zero-flow criterion, termed zero-flow discrepancy (ZFD). We prove the validity of ZFD and propose a practical testing procedure, termed the zero-flow two-sample test (ZF2ST). The key idea is to learn how samples from the two distributions are locally misaligned and use the resulting directional pattern as evidence of distributional difference. By separating witness learning from hypothesis evaluation, ZF2ST can use flexible neural networks while maintaining valid statistical calibration. We develop both regression-based and power-maximized approaches for learning the witness. Experiments on synthetic and image datasets demonstrate that ZF2ST can achieve strong testing power for structured distributional changes while maintaining well-calibrated type-I error. less
By: Dongjie Fu, Di Cao, Xize Cheng, Zihan Zhang, Wenxu Jia, Yifu Chen, Shengpeng Ji, Yu Zhang, Tao Jin
While large audio-language models have achieved remarkable progress in auditory perception, they still lag behind text-based large language models in deep logical reasoning, primarily due to the scarcity of high-quality audio reasoning data. To bridge this gap, we propose X$^3$-OPD, a cross-modal on-policy distillation framework that transfers reasoning capabilities from a powerful text teacher to an audio-language student. During training, t... more
While large audio-language models have achieved remarkable progress in auditory perception, they still lag behind text-based large language models in deep logical reasoning, primarily due to the scarcity of high-quality audio reasoning data. To bridge this gap, we propose X$^3$-OPD, a cross-modal on-policy distillation framework that transfers reasoning capabilities from a powerful text teacher to an audio-language student. During training, the student generates reasoning trajectories conditioned on its own acoustic perception, while the teacher provides token-level guidance using matched textual inputs and verified answers. We further construct a three-tier symmetric corpus covering textual reasoning rendered into speech, audio-event reasoning grounded in complex acoustic scenes, and spoken-dialogue reasoning involving paralinguistic cues. This design extends cross-modal distillation beyond textually recoverable content to reasoning grounded in non-linguistic events, prosody, and conversational context. Experiments on MMSU, MMAU, BIG Bench Audio, and MMAR demonstrate that X$^3$-OPD substantially improves audio-grounded reasoning and chain-of-thought quality while largely preserving the model's existing capabilities under domain shift. less
By: Hongnan Ma, Yiwei Shi, Mengyue Yang, Weiru Liu
Faithful explanations of time-series classifiers should identify subsequences that are not only sufficient to preserve a black-box model's prediction, but also necessary for maintaining it. However, existing sufficiency-oriented methods can assign high importance to spurious subsequences that support the prediction without being essential to the model's decision. We introduce \textbf{TimePNS}, a necessity-aware framework for time-series expla... more
Faithful explanations of time-series classifiers should identify subsequences that are not only sufficient to preserve a black-box model's prediction, but also necessary for maintaining it. However, existing sufficiency-oriented methods can assign high importance to spurious subsequences that support the prediction without being essential to the model's decision. We introduce \textbf{TimePNS}, a necessity-aware framework for time-series explanation. Inspired by Pearl's counterfactual notion of necessity, TimePNS assesses whether a temporal factor is necessary by intervening on it and measuring whether the original prediction is disrupted. The framework adopts a two-stage design. Stage I learns an identifiable causal generative process together with a sufficiency-oriented explanation mask. Stage II performs counterfactual interventions on temporal factors to derive necessity signals, which supervise a temporal gate that refines the initial explanation by suppressing non-essential components and emphasizing counterfactually necessary ones. Experiments on synthetic and real-world time-series benchmarks show that TimePNS more accurately identifies decision-critical subsequences and consistently improves sufficiency-necessity trade-offs over strong baselines. less
Expanding Flow Maps
0upvotes
By: Sophia Tang, Pranam Chatterjee
Flow-based generative models have enabled remarkable progress in fast and controllable generation across continuous and discrete state spaces, yet existing parameterizations are constrained to fixed dimensions or fixed sequence lengths. Here, we introduce Expanding Generative Flows (EFlows), which define flows between distributions of increasing dimensionality along an expanding interpolant that grows the state by augmenting it with condition... more
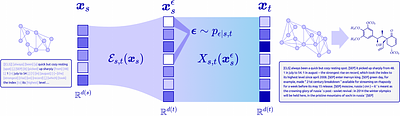
Flow-based generative models have enabled remarkable progress in fast and controllable generation across continuous and discrete state spaces, yet existing parameterizations are constrained to fixed dimensions or fixed sequence lengths. Here, we introduce Expanding Generative Flows (EFlows), which define flows between distributions of increasing dimensionality along an expanding interpolant that grows the state by augmenting it with conditional noise. Building on this construction, we propose Expanding Flow Maps (EFMs), a new class of flow maps that distill the expanding interpolant into efficient few-step generative models. Each EFM factors the map between any two timesteps into two learnable operations: an expand operator, which augments the state space with new coordinates or tokens conditioned on the current state, and a transport map, which pushes the expanded state forward along the interpolant. Composing these operators yields a single map that jointly expands and denoises the state, recovering existing fixed-canvas flows and flow maps as the special case in which the expand operator is the identity. We further extend the framework to the discrete simplex, enabling variable-size graph generation and variable-length sequence generation. Across both continuous and discrete modalities, we establish EFlows and EFMs as a principled framework for settings in which output size is itself a learned, controllable degree of freedom. less
By: Martin Anthony, Kaveh Salehzadeh Nobari
An initial high-recall stage in an empirical pipeline decides which items pass to later review, labelling, or modelling, and relevant items it misses are lost to every subsequent stage. We study how many audit labels are needed to certify, with finite-sample validity, that this missed relevant mass is small, and our main results characterise the label complexity of this problem. We first show that no procedure using only labels from inside th... more
An initial high-recall stage in an empirical pipeline decides which items pass to later review, labelling, or modelling, and relevant items it misses are lost to every subsequent stage. We study how many audit labels are needed to certify, with finite-sample validity, that this missed relevant mass is small, and our main results characterise the label complexity of this problem. We first show that no procedure using only labels from inside the candidate set can certify any non-trivial bound on the missed mass: the audit must sample the excluded pool, the only region where unrecovered relevant items can lie. We then prove a matching finite-corpus lower bound. Any valid audit that certifies fewer than $m$ missed relevant items with high probability when none are present, even if adaptive and permitted to label the entire included pool, must inspect on the order of $N_0/m$ excluded-pool labels. Excluded-pool auditing is therefore minimax rate-optimal, not merely convenient, for missed-mass certification in the zero-miss regime. Building on this characterisation, we develop an exact finite-sample toolkit, using binomial and hypergeometric inversion rather than asymptotic approximation, that certifies missed mass, converts it to recall through a two-pool design, certifies pre-specified families of nested candidate generators simultaneously, and produces stress-test certificates against declared perturbation mechanisms. These certificates can be paired with observable review burden to select the least burdensome pre-specified candidate generator meeting a missed-mass target. Every guarantee holds under one discipline: the candidate generator, or the pre-specified family from which it is selected, and the audit rule are fixed before the certification labels are examined. less
By: Daniil Cherniavskii, Daniel Severo, Karen Ullrich
Discrete flow matching provides a flexible framework for generative modeling on discrete structures. However, the standard factorized training objective exposes the model to targets of varying difficulty, mixing well-conditioned, predictable tokens with ambiguous, high-entropy ones. We empirically demonstrate that the uncertainty over the value of each token is closely related to the density of available context in its neighborhood. Motivated... more
Discrete flow matching provides a flexible framework for generative modeling on discrete structures. However, the standard factorized training objective exposes the model to targets of varying difficulty, mixing well-conditioned, predictable tokens with ambiguous, high-entropy ones. We empirically demonstrate that the uncertainty over the value of each token is closely related to the density of available context in its neighborhood. Motivated by this observation, we propose a simple modification to the underlying continuous-time Markov chain (CTMC) that incorporates local context information. Our context-weighted sampler improves generation quality with negligible computational overhead, while our scaled cross-entropy loss function reweights the training signal from different tokens and reduces generative perplexity by up to 63% on OpenWebText. Moreover, our approach matches a strong semi-autoregressive block diffusion baseline in quality while retaining the ability to perform generation in any order. These results highlight the role of local context as an important factor in discrete generative modeling and show that simple context-aware modifications can significantly improve both sampling and training efficiency. less
By: Mohammed Suhail B Nadaf
Fine-tuning an aligned language model on a narrow stream of bad advice can make it broadly misaligned on questions unrelated to the training data, a phenomenon called emergent misalignment. We ask why the narrow lesson generalizes at all, and we find that narrow fine-tuning recruits a persona structure that is present in the model before the fine-tune exists. From a frozen instruction-tuned model (Qwen2.5-14B-Instruct) we extract per-domain p... more
Fine-tuning an aligned language model on a narrow stream of bad advice can make it broadly misaligned on questions unrelated to the training data, a phenomenon called emergent misalignment. We ask why the narrow lesson generalizes at all, and we find that narrow fine-tuning recruits a persona structure that is present in the model before the fine-tune exists. From a frozen instruction-tuned model (Qwen2.5-14B-Instruct) we extract per-domain persona subspaces by contrastive teacher forcing and find that 4 unrelated domains share one low-rank core at 657x a random-subspace null, with 82% of that core lying outside a style core built at matched diversity. The literal first optimizer step of fine-tuning on insecure code climbs a broad-misalignment margin harder than the same code framed as educational, and forecasts realized margin movement out to 375 steps. Projecting the subspace out of the residual stream throughout fine-tuning prevents broad misalignment (27.7% to 0.0% of judged generations) while a matched-rank random subspace changes nothing; injecting it into the never-fine-tuned model induces misalignment that grows with dose to 45.4%, past the fine-tuned model it is measured against. The same projection applied to the weight gradient is inert, and three post-hoc weight edits leave the disposition in place: the sharpest edit suppresses the behavior rather than removing it, and the ablated structure re-forms inside the subspace the edit cleared. Spreading a fixed budget of bad data across 4 domains produces more broad misalignment than mechanical weight superposition and matched diversity jointly account for. All measurements come from one model at 14B; the extraction is from an aligned instruction-tuned checkpoint, which leaves the structure's provenance open; and the intervention that prevents misalignment also abolishes the narrow trained behavior. less