



Graph Learning on Ensembles of Cyclic Peptides: An Investigation of Molecular Ensemble Modeling
0upvotes
By: Aaron Feller, Kris Deibler, Maxim Secor
Molecular property prediction from structure often uses a single representative conformation, even though many molecules exist as conformational ensembles in solution. We introduce EnsembleEGNN, a molecular ensemble foundation model that encodes an ensemble by first encoding each conformer with shared Equivariant Graph Neural Network (EGNN) layers, then pooling the resulting conformer representations with a Set Attention Block. We pretrain th... more
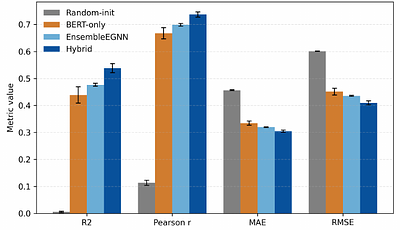
Molecular property prediction from structure often uses a single representative conformation, even though many molecules exist as conformational ensembles in solution. We introduce EnsembleEGNN, a molecular ensemble foundation model that encodes an ensemble by first encoding each conformer with shared Equivariant Graph Neural Network (EGNN) layers, then pooling the resulting conformer representations with a Set Attention Block. We pretrain the model on CREMP, a cyclic peptide ensemble dataset, using a multi-task self-supervised objective combining masked token recovery, noisy-coordinate reconstruction, and pairwise distance reconstruction. On the CREMP-CycPeptMPDB dataset, training EnsembleEGNN from scratch fails entirely ($R^2=0.005$). However, the pretrained model reaches $R^2=0.477$ and Pearson $r=0.699$, outperforming the sequence-only BERT baseline ($R^2=0.439$, Pearson $r=0.667$). When EnsembleEGNN is co-trained end-to-end with the BERT sequence encoder, the hybrid model improves further to $R^2=0.538$ and Pearson $r=0.737$. These results demonstrate that encoding conformational ensembles into a single thermodynamically informed embedding improves cyclic-peptide property prediction. less
Zero-Flow Two-Sample Tests
0upvotes
By: Yakun Wang, Leyang Wang, Song Liu, Taiji Suzuki
We propose a new approach to two-sample testing for deciding whether two sets of samples are drawn from the same distribution. The test is built on a statistical discrepancy based on the zero-flow criterion, termed zero-flow discrepancy (ZFD). We prove the validity of ZFD and propose a practical testing procedure, termed the zero-flow two-sample test (ZF2ST). The key idea is to learn how samples from the two distributions are locally misalign... more
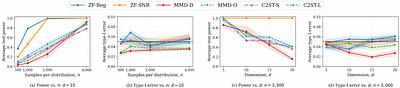
We propose a new approach to two-sample testing for deciding whether two sets of samples are drawn from the same distribution. The test is built on a statistical discrepancy based on the zero-flow criterion, termed zero-flow discrepancy (ZFD). We prove the validity of ZFD and propose a practical testing procedure, termed the zero-flow two-sample test (ZF2ST). The key idea is to learn how samples from the two distributions are locally misaligned and use the resulting directional pattern as evidence of distributional difference. By separating witness learning from hypothesis evaluation, ZF2ST can use flexible neural networks while maintaining valid statistical calibration. We develop both regression-based and power-maximized approaches for learning the witness. Experiments on synthetic and image datasets demonstrate that ZF2ST can achieve strong testing power for structured distributional changes while maintaining well-calibrated type-I error. less
By: Dongjie Fu, Di Cao, Xize Cheng, Zihan Zhang, Wenxu Jia, Yifu Chen, Shengpeng Ji, Yu Zhang, Tao Jin
While large audio-language models have achieved remarkable progress in auditory perception, they still lag behind text-based large language models in deep logical reasoning, primarily due to the scarcity of high-quality audio reasoning data. To bridge this gap, we propose X$^3$-OPD, a cross-modal on-policy distillation framework that transfers reasoning capabilities from a powerful text teacher to an audio-language student. During training, t... more
While large audio-language models have achieved remarkable progress in auditory perception, they still lag behind text-based large language models in deep logical reasoning, primarily due to the scarcity of high-quality audio reasoning data. To bridge this gap, we propose X$^3$-OPD, a cross-modal on-policy distillation framework that transfers reasoning capabilities from a powerful text teacher to an audio-language student. During training, the student generates reasoning trajectories conditioned on its own acoustic perception, while the teacher provides token-level guidance using matched textual inputs and verified answers. We further construct a three-tier symmetric corpus covering textual reasoning rendered into speech, audio-event reasoning grounded in complex acoustic scenes, and spoken-dialogue reasoning involving paralinguistic cues. This design extends cross-modal distillation beyond textually recoverable content to reasoning grounded in non-linguistic events, prosody, and conversational context. Experiments on MMSU, MMAU, BIG Bench Audio, and MMAR demonstrate that X$^3$-OPD substantially improves audio-grounded reasoning and chain-of-thought quality while largely preserving the model's existing capabilities under domain shift. less
By: Hongnan Ma, Yiwei Shi, Mengyue Yang, Weiru Liu
Faithful explanations of time-series classifiers should identify subsequences that are not only sufficient to preserve a black-box model's prediction, but also necessary for maintaining it. However, existing sufficiency-oriented methods can assign high importance to spurious subsequences that support the prediction without being essential to the model's decision. We introduce \textbf{TimePNS}, a necessity-aware framework for time-series expla... more
Faithful explanations of time-series classifiers should identify subsequences that are not only sufficient to preserve a black-box model's prediction, but also necessary for maintaining it. However, existing sufficiency-oriented methods can assign high importance to spurious subsequences that support the prediction without being essential to the model's decision. We introduce \textbf{TimePNS}, a necessity-aware framework for time-series explanation. Inspired by Pearl's counterfactual notion of necessity, TimePNS assesses whether a temporal factor is necessary by intervening on it and measuring whether the original prediction is disrupted. The framework adopts a two-stage design. Stage I learns an identifiable causal generative process together with a sufficiency-oriented explanation mask. Stage II performs counterfactual interventions on temporal factors to derive necessity signals, which supervise a temporal gate that refines the initial explanation by suppressing non-essential components and emphasizing counterfactually necessary ones. Experiments on synthetic and real-world time-series benchmarks show that TimePNS more accurately identifies decision-critical subsequences and consistently improves sufficiency-necessity trade-offs over strong baselines. less