Are Large Language Models Robust in Understanding Code Against
  Semantics-Preserving Mutations?

By: Pedro Orvalho, Marta Kwiatkowska

Understanding the reasoning and robustness of Large Language Models (LLMs) is critical for their reliable use in programming tasks. While recent studies have assessed LLMs' ability to predict program outputs, most focus solely on the accuracy of those predictions, without evaluating the reasoning behind them. Moreover, it has been observed on mathematical reasoning tasks that LLMs can arrive at correct answers through flawed logic, raising co... more
Understanding the reasoning and robustness of Large Language Models (LLMs) is critical for their reliable use in programming tasks. While recent studies have assessed LLMs' ability to predict program outputs, most focus solely on the accuracy of those predictions, without evaluating the reasoning behind them. Moreover, it has been observed on mathematical reasoning tasks that LLMs can arrive at correct answers through flawed logic, raising concerns about similar issues in code understanding. In this work, we evaluate whether state-of-the-art LLMs with up to 8B parameters can reason about Python programs or are simply guessing. We apply five semantics-preserving code mutations: renaming variables, mirroring comparison expressions, swapping if-else branches, converting for loops to while, and loop unrolling. These mutations maintain program semantics while altering its syntax. We evaluated six LLMs and performed a human expert analysis using LiveCodeBench to assess whether the correct predictions are based on sound reasoning. We also evaluated prediction stability across different code mutations on LiveCodeBench and CruxEval. Our findings show that some LLMs, such as Llama3.2, produce correct predictions based on flawed reasoning in up to 61% of cases. Furthermore, LLMs often change predictions in response to our code mutations, indicating limited robustness in their semantic understanding. less
Pitfalls in Language Models for Code Intelligence: A Taxonomy and Survey

By: Xinyu She, Yue Liu, Yanjie Zhao, Yiling He, Li Li, Chakkrit Tantithamthavorn, Zhan Qin, Haoyu Wang

Modern language models (LMs) have been successfully employed in source code generation and understanding, leading to a significant increase in research focused on learning-based code intelligence, such as automated bug repair, and test case generation. Despite their great potential, language models for code intelligence (LM4Code) are susceptible to potential pitfalls, which hinder realistic performance and further impact their reliability a... more
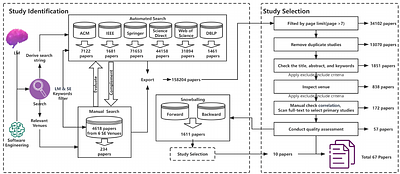
Modern language models (LMs) have been successfully employed in source code generation and understanding, leading to a significant increase in research focused on learning-based code intelligence, such as automated bug repair, and test case generation. Despite their great potential, language models for code intelligence (LM4Code) are susceptible to potential pitfalls, which hinder realistic performance and further impact their reliability and applicability in real-world deployment. Such challenges drive the need for a comprehensive understanding - not just identifying these issues but delving into their possible implications and existing solutions to build more reliable language models tailored to code intelligence. Based on a well-defined systematic research approach, we conducted an extensive literature review to uncover the pitfalls inherent in LM4Code. Finally, 67 primary studies from top-tier venues have been identified. After carefully examining these studies, we designed a taxonomy of pitfalls in LM4Code research and conducted a systematic study to summarize the issues, implications, current solutions, and challenges of different pitfalls for LM4Code systems. We developed a comprehensive classification scheme that dissects pitfalls across four crucial aspects: data collection and labeling, system design and learning, performance evaluation, and deployment and maintenance. Through this study, we aim to provide a roadmap for researchers and practitioners, facilitating their understanding and utilization of LM4Code in reliable and trustworthy ways. less
Runtime Resolution of Feature Interactions through Adaptive Requirement
  Weakening

By: Simon Chu, Emma Shedden, Changjian Zhang, Rômulo Meira-Góes, Gabriel A. Moreno, David Garlan, Eunsuk Kang

The feature interaction problem occurs when two or more independently developed components interact with each other in unanticipated ways, resulting in undesirable system behaviors. Feature interaction problems remain a challenge for emerging domains in cyber-physical systems (CPS), such as the Internet of Things and autonomous drones. Existing techniques for resolving feature interactions take a "winner-takes-all" approach, where one out o... more
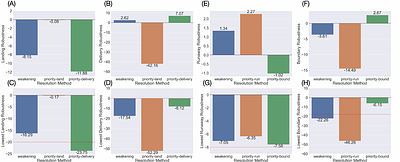
The feature interaction problem occurs when two or more independently developed components interact with each other in unanticipated ways, resulting in undesirable system behaviors. Feature interaction problems remain a challenge for emerging domains in cyber-physical systems (CPS), such as the Internet of Things and autonomous drones. Existing techniques for resolving feature interactions take a "winner-takes-all" approach, where one out of the conflicting features is selected as the most desirable one, and the rest are disabled. However, when multiple of the conflicting features fulfill important system requirements, being forced to select one of them can result in an undesirable system outcome. In this paper, we propose a new resolution approach that allows all of the conflicting features to continue to partially fulfill their requirements during the resolution process. In particular, our approach leverages the idea of adaptive requirement weakening, which involves one or more features temporarily weakening their level of performance in order to co-exist with the other features in a consistent manner. Given feature requirements specified in Signal Temporal Logic (STL), we propose an automated method and a runtime architecture for automatically weakening the requirements to resolve a conflict. We demonstrate our approach through case studies on feature interactions in autonomous drones. less
Demystifying Compiler Unstable Feature Usage and Impacts in the Rust
  Ecosystem

By: Chenghao Li Zhejiang University, Hangzhou, China, Yifei Wu Zhejiang University, Hangzhou, China, Wenbo Shen Zhejiang University, Hangzhou, China, Zichen Zhao Zhejiang University, Hangzhou, China, Rui Chang Zhejiang University, Hangzhou, China, Chengwei Liu Nanyang Technological University, Singapore, Singapore, Yang Liu Nanyang Technological University, Singapore, Singapore, Kui Ren Zhejiang University, Hangzhou, China

Rust programming language is gaining popularity rapidly in building reliable and secure systems due to its security guarantees and outstanding performance. To provide extra functionalities, the Rust compiler introduces Rust unstable features (RUF) to extend compiler functionality, syntax, and standard library support. However, these features are unstable and may get removed, introducing compilation failures to dependent packages. Even worse... more
Rust programming language is gaining popularity rapidly in building reliable and secure systems due to its security guarantees and outstanding performance. To provide extra functionalities, the Rust compiler introduces Rust unstable features (RUF) to extend compiler functionality, syntax, and standard library support. However, these features are unstable and may get removed, introducing compilation failures to dependent packages. Even worse, their impacts propagate through transitive dependencies, causing large-scale failures in the whole ecosystem. Although RUF is widely used in Rust, previous research has primarily concentrated on Rust code safety, with the usage and impacts of RUF from the Rust compiler remaining unexplored. Therefore, we aim to bridge this gap by systematically analyzing the RUF usage and impacts in the Rust ecosystem. We propose novel techniques for extracting RUF precisely, and to assess its impact on the entire ecosystem quantitatively, we accurately resolve package dependencies. We have analyzed the whole Rust ecosystem with 590K package versions and 140M transitive dependencies. Our study shows that the Rust ecosystem uses 1000 different RUF, and at most 44% of package versions are affected by RUF, causing compiling failures for at most 12%. To mitigate wide RUF impacts, we further design and implement a RUF-compilation-failure recovery tool that can recover up to 90% of the failure. We believe our techniques, findings, and tools can help to stabilize the Rust compiler, ultimately enhancing the security and reliability of the Rust ecosystem. less
Towards the decentralized coordination of multiple self-adaptive systems

By: Paul-Andrei Dragan, Andreas Metzger, Klaus Pohl

When multiple self-adaptive systems share the same environment and have common goals, they may coordinate their adaptations at runtime to avoid conflicts and to satisfy their goals. There are two approaches to coordination. (1) Logically centralized, where a supervisor has complete control over the individual self-adaptive systems. Such approach is infeasible when the systems have different owners or administrative domains. (2) Logically de... more
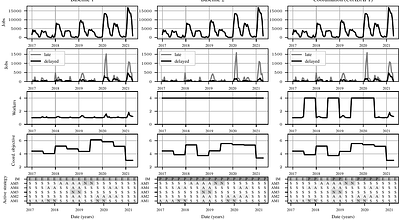
When multiple self-adaptive systems share the same environment and have common goals, they may coordinate their adaptations at runtime to avoid conflicts and to satisfy their goals. There are two approaches to coordination. (1) Logically centralized, where a supervisor has complete control over the individual self-adaptive systems. Such approach is infeasible when the systems have different owners or administrative domains. (2) Logically decentralized, where coordination is achieved through direct interactions. Because the individual systems have control over the information they share, decentralized coordination accommodates multiple administrative domains. However, existing techniques do not account simultaneously for both local concerns, e.g., preferences, and shared concerns, e.g., conflicts, which may lead to goals not being achieved as expected. Our idea to address this shortcoming is to express both types of concerns within the same constraint optimization problem. We propose CoADAPT, a decentralized coordination technique introducing two types of constraints: preference constraints, expressing local concerns, and consistency constraints, expressing shared concerns. At runtime, the problem is solved in a decentralized way using distributed constraint optimization algorithms implemented by each self-adaptive system. As a first step in realizing CoADAPT, we focus in this work on the coordination of adaptation planning strategies, traditionally addressed only with centralized techniques. We show the feasibility of CoADAPT in an exemplar from cloud computing and analyze experimentally its scalability. less
Variance of ML-based software fault predictors: are we really improving
  fault prediction?

By: Xhulja Shahini, Domenic Bubel, Andreas Metzger

Software quality assurance activities become increasingly difficult as software systems become more and more complex and continuously grow in size. Moreover, testing becomes even more expensive when dealing with large-scale systems. Thus, to effectively allocate quality assurance resources, researchers have proposed fault prediction (FP) which utilizes machine learning (ML) to predict fault-prone code areas. However, ML algorithms typically... more
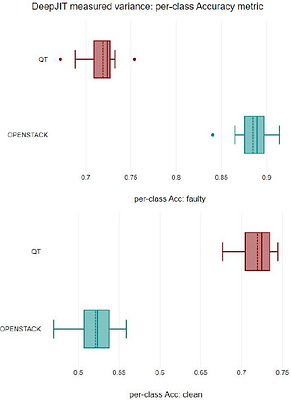
Software quality assurance activities become increasingly difficult as software systems become more and more complex and continuously grow in size. Moreover, testing becomes even more expensive when dealing with large-scale systems. Thus, to effectively allocate quality assurance resources, researchers have proposed fault prediction (FP) which utilizes machine learning (ML) to predict fault-prone code areas. However, ML algorithms typically make use of stochastic elements to increase the prediction models' generalizability and efficiency of the training process. These stochastic elements, also known as nondeterminism-introducing (NI) factors, lead to variance in the training process and as a result, lead to variance in prediction accuracy and training time. This variance poses a challenge for reproducibility in research. More importantly, while fault prediction models may have shown good performance in the lab (e.g., often-times involving multiple runs and averaging outcomes), high variance of results can pose the risk that these models show low performance when applied in practice. In this work, we experimentally analyze the variance of a state-of-the-art fault prediction approach. Our experimental results indicate that NI factors can indeed cause considerable variance in the fault prediction models' accuracy. We observed a maximum variance of 10.10% in terms of the per-class accuracy metric. We thus, also discuss how to deal with such variance. less
Exploring Behaviours of RESTful APIs in an Industrial Setting

By: Stefan Karlsson, Robbert Jongeling, Adnan Causevic, Daniel Sundmark

A common way of exposing functionality in contemporary systems is by providing a Web-API based on the REST API architectural guidelines. To describe REST APIs, the industry standard is currently OpenAPI-specifications. Test generation and fuzzing methods targeting OpenAPI-described REST APIs have been a very active research area in recent years. An open research challenge is to aid users in better understanding their API, in addition to fin... more
A common way of exposing functionality in contemporary systems is by providing a Web-API based on the REST API architectural guidelines. To describe REST APIs, the industry standard is currently OpenAPI-specifications. Test generation and fuzzing methods targeting OpenAPI-described REST APIs have been a very active research area in recent years. An open research challenge is to aid users in better understanding their API, in addition to finding faults and to cover all the code. In this paper, we address this challenge by proposing a set of behavioural properties, common to REST APIs, which are used to generate examples of behaviours that these APIs exhibit. These examples can be used both (i) to further the understanding of the API and (ii) as a source of automatic test cases. Our evaluation shows that our approach can generate examples deemed relevant for understanding the system and for a source of test generation by practitioners. In addition, we show that basing test generation on behavioural properties provides tests that are less dependent on the state of the system, while at the same time yielding a similar code coverage as state-of-the-art methods in REST API fuzzing in a given time limit. less