GRAPE-S: Near Real-Time Coalition Formation for Multiple Service
  Collectives

By: Grace Diehl, Julie A. Adams

Robotic collectives for military and disaster response applications require coalition formation algorithms to partition robots into appropriate task teams. Collectives' missions will often incorporate tasks that require multiple high-level robot behaviors or services, which coalition formation must accommodate. The highly dynamic and unstructured application domains also necessitate that coalition formation algorithms produce near optimal s... more
Robotic collectives for military and disaster response applications require coalition formation algorithms to partition robots into appropriate task teams. Collectives' missions will often incorporate tasks that require multiple high-level robot behaviors or services, which coalition formation must accommodate. The highly dynamic and unstructured application domains also necessitate that coalition formation algorithms produce near optimal solutions (i.e., >95% utility) in near real-time (i.e., <5 minutes) with very large collectives (i.e., hundreds of robots). No previous coalition formation algorithm satisfies these requirements. An initial evaluation found that traditional auction-based algorithms' runtimes are too long, even though the centralized simulator incorporated ideal conditions unlikely to occur in real-world deployments (i.e., synchronization across robots and perfect, instantaneous communication). The hedonic game-based GRAPE algorithm can produce solutions in near real-time, but cannot be applied to multiple service collectives. This manuscript integrates GRAPE and a services model, producing GRAPE-S and Pair-GRAPE-S. These algorithms and two auction baselines were evaluated using a centralized simulator with up to 1000 robots, and via the largest distributed coalition formation simulated evaluation to date, with up to 500 robots. The evaluations demonstrate that auctions transfer poorly to distributed collectives, resulting in excessive runtimes and low utility solutions. GRAPE-S satisfies the target domains' coalition formation requirements, producing near optimal solutions in near real-time, and Pair-GRAPE-S more than satisfies the domain requirements, producing optimal solutions in near real-time. GRAPE-S and Pair-GRAPE-S are the first algorithms demonstrated to support near real-time coalition formation for very large, distributed collectives with multiple services. less
Cormas: The Software for Participatory Modelling and its Application for
  Managing Natural Resources in Senegal

By: Oleksandr Zaitsev SENS, Cirad, UM, François Vendel Cirad, SENS, ISRA, CNRF, Etienne Delay UPR GREEN, Cirad, SENS, ESP, UMMISCO

Cormas is an agent-based simulation platform developed in the late 90s by the Green research at CIRAD unit to support the management of natural resources and understand the interactions between natural and social dynamics. This platform is well-suited for a participatory simulation approach that empowers local stakeholders by including them in all modelling and knowledge-sharing steps. In this short paper, we present the Cormas platform and... more
Cormas is an agent-based simulation platform developed in the late 90s by the Green research at CIRAD unit to support the management of natural resources and understand the interactions between natural and social dynamics. This platform is well-suited for a participatory simulation approach that empowers local stakeholders by including them in all modelling and knowledge-sharing steps. In this short paper, we present the Cormas platform and discuss its unique features and their importance for the participatory simulation approach. We then present the early results of our ongoing study on managing pastoral resources in the Sahel region, identify the problems faced by local stakeholders, and discuss the potential use of Cormas at the next stage of our study to collectively model and understand the effective ways of managing the shared agro-sylvo-pastoral resources. less
Impact of Relational Networks in Multi-Agent Learning: A Value-Based
  Factorization View

By: Yasin Findik, Paul Robinette, Kshitij Jerath, S. Reza Ahmadzadeh

Effective coordination and cooperation among agents are crucial for accomplishing individual or shared objectives in multi-agent systems. In many real-world multi-agent systems, agents possess varying abilities and constraints, making it necessary to prioritize agents based on their specific properties to ensure successful coordination and cooperation within the team. However, most existing cooperative multi-agent algorithms do not take int... more
Effective coordination and cooperation among agents are crucial for accomplishing individual or shared objectives in multi-agent systems. In many real-world multi-agent systems, agents possess varying abilities and constraints, making it necessary to prioritize agents based on their specific properties to ensure successful coordination and cooperation within the team. However, most existing cooperative multi-agent algorithms do not take into account these individual differences, and lack an effective mechanism to guide coordination strategies. We propose a novel multi-agent learning approach that incorporates relationship awareness into value-based factorization methods. Given a relational network, our approach utilizes inter-agents relationships to discover new team behaviors by prioritizing certain agents over other, accounting for differences between them in cooperative tasks. We evaluated the effectiveness of our proposed approach by conducting fifteen experiments in two different environments. The results demonstrate that our proposed algorithm can influence and shape team behavior, guide cooperation strategies, and expedite agent learning. Therefore, our approach shows promise for use in multi-agent systems, especially when agents have diverse properties. less
MARVEL: Multi-Agent Reinforcement-Learning for Large-Scale Variable
  Speed Limits

By: Yuhang Zhang, Marcos Quinones-Grueiro, Zhiyao Zhang, Yanbing Wang, William Barbour, Gautam Biswas, Daniel Work

Variable speed limit (VSL) control is a promising traffic management strategy for enhancing safety and mobility. This work introduces MARVEL, a multi-agent reinforcement learning (MARL) framework for implementing large-scale VSL control on freeway corridors using only commonly available data. The agents learn through a reward structure that incorporates adaptability to traffic conditions, safety, and mobility; enabling coordination among th... more
Variable speed limit (VSL) control is a promising traffic management strategy for enhancing safety and mobility. This work introduces MARVEL, a multi-agent reinforcement learning (MARL) framework for implementing large-scale VSL control on freeway corridors using only commonly available data. The agents learn through a reward structure that incorporates adaptability to traffic conditions, safety, and mobility; enabling coordination among the agents. The proposed framework scales to cover corridors with many gantries thanks to a parameter sharing among all VSL agents. The agents are trained in a microsimulation environment based on a short freeway stretch with 8 gantries spanning 7 miles and tested with 34 gantries spanning 17 miles of I-24 near Nashville, TN. MARVEL improves traffic safety by 63.4% compared to the no control scenario and enhances traffic mobility by 14.6% compared to a state-of-the-practice algorithm that has been deployed on I-24. An explainability analysis is undertaken to explore the learned policy under different traffic conditions and the results provide insights into the decision-making process of agents. Finally, we test the policy learned from the simulation-based experiments on real input data from I-24 to illustrate the potential deployment capability of the learned policy. less
Welfare Diplomacy: Benchmarking Language Model Cooperation

By: Gabriel Mukobi, Hannah Erlebach, Niklas Lauffer, Lewis Hammond, Alan Chan, Jesse Clifton

The growing capabilities and increasingly widespread deployment of AI systems necessitate robust benchmarks for measuring their cooperative capabilities. Unfortunately, most multi-agent benchmarks are either zero-sum or purely cooperative, providing limited opportunities for such measurements. We introduce a general-sum variant of the zero-sum board game Diplomacy -- called Welfare Diplomacy -- in which players must balance investing in mil... more
The growing capabilities and increasingly widespread deployment of AI systems necessitate robust benchmarks for measuring their cooperative capabilities. Unfortunately, most multi-agent benchmarks are either zero-sum or purely cooperative, providing limited opportunities for such measurements. We introduce a general-sum variant of the zero-sum board game Diplomacy -- called Welfare Diplomacy -- in which players must balance investing in military conquest and domestic welfare. We argue that Welfare Diplomacy facilitates both a clearer assessment of and stronger training incentives for cooperative capabilities. Our contributions are: (1) proposing the Welfare Diplomacy rules and implementing them via an open-source Diplomacy engine; (2) constructing baseline agents using zero-shot prompted language models; and (3) conducting experiments where we find that baselines using state-of-the-art models attain high social welfare but are exploitable. Our work aims to promote societal safety by aiding researchers in developing and assessing multi-agent AI systems. Code to evaluate Welfare Diplomacy and reproduce our experiments is available at https://github.com/mukobi/welfare-diplomacy. less
Multi-Value Alignment in Normative Multi-Agent System: An Evolutionary
  Optimisation Approach

By: Maha Riad, Vinicius de Carvalho, Fatemeh Golpayegani

Value-alignment in normative multi-agent systems is used to promote a certain value and to ensure the consistent behaviour of agents in autonomous intelligent systems with human values. However, the current literature is limited to the incorporation of effective norms for single-value alignment with no consideration of agents' heterogeneity and the requirement of simultaneous promotion and alignment of multiple values. This research propose... more
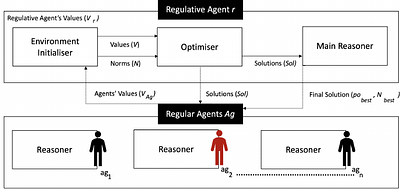
Value-alignment in normative multi-agent systems is used to promote a certain value and to ensure the consistent behaviour of agents in autonomous intelligent systems with human values. However, the current literature is limited to the incorporation of effective norms for single-value alignment with no consideration of agents' heterogeneity and the requirement of simultaneous promotion and alignment of multiple values. This research proposes a multi-value promotion model that uses multi-objective evolutionary algorithms and decentralised reasoning to produce the optimum parametric set of norms that is aligned with multiple simultaneous values of heterogeneous agents and the system. To understand various aspects of this complex problem, several evolutionary algorithms were used to find a set of optimised norm parameters considering two toy tax scenarios with two and five values are considered. The results are analysed from different perspectives to show the impact of a selected evolutionary algorithm on the solution, and the importance of understanding the relation between values when prioritising them. less
Community Consensus: Converging Locally despite Adversaries and
  Heterogeneous Connectivity

By: Cristina Gava, Aron Vekassy, Matthew Cavorsi, Stephanie Gil, Frederik Mallmann-Trenn

We introduce the concept of community consensus in the presence of malicious agents using a well-known median-based consensus algorithm. We consider networks that have multiple well-connected regions that we term communities, characterized by specific robustness and minimum degree properties. Prior work derives conditions on properties that are necessary and sufficient for achieving global consensus in a network. This however, requires the ... more
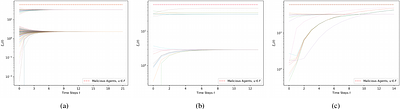
We introduce the concept of community consensus in the presence of malicious agents using a well-known median-based consensus algorithm. We consider networks that have multiple well-connected regions that we term communities, characterized by specific robustness and minimum degree properties. Prior work derives conditions on properties that are necessary and sufficient for achieving global consensus in a network. This however, requires the minimum degree of the network graph to be proportional to the number of malicious agents in the network, which is not very practical in large networks. In this work we present a natural generalization of this previous result. We characterize cases when although global consensus is not reached, some subsets of agents $V_i$ will still converge to the same values $\mathcal{M}_i$ among themselves. We define more relaxed requirements for this new type of consensus to be reached in terms of the number $k$ of edges connecting an agent in a community to agents external to the community, and the number of malicious agents in each community. less
Quantifying Agent Interaction in Multi-agent Reinforcement Learning for
  Cost-efficient Generalization

By: Yuxin Chen, Chen Tang, Ran Tian, Chenran Li, Jinning Li, Masayoshi Tomizuka, Wei Zhan

Generalization poses a significant challenge in Multi-agent Reinforcement Learning (MARL). The extent to which an agent is influenced by unseen co-players depends on the agent's policy and the specific scenario. A quantitative examination of this relationship sheds light on effectively training agents for diverse scenarios. In this study, we present the Level of Influence (LoI), a metric quantifying the interaction intensity among agents wi... more
Generalization poses a significant challenge in Multi-agent Reinforcement Learning (MARL). The extent to which an agent is influenced by unseen co-players depends on the agent's policy and the specific scenario. A quantitative examination of this relationship sheds light on effectively training agents for diverse scenarios. In this study, we present the Level of Influence (LoI), a metric quantifying the interaction intensity among agents within a given scenario and environment. We observe that, generally, a more diverse set of co-play agents during training enhances the generalization performance of the ego agent; however, this improvement varies across distinct scenarios and environments. LoI proves effective in predicting these improvement disparities within specific scenarios. Furthermore, we introduce a LoI-guided resource allocation method tailored to train a set of policies for diverse scenarios under a constrained budget. Our results demonstrate that strategic resource allocation based on LoI can achieve higher performance than uniform allocation under the same computation budget. less
Leader-Follower Formation Control of Perturbed Nonholonomic Agents along
  Parametric Curves with Directed Communication

By: Bin Zhang, Hui Zhi, Jose Guadalupe Romero, David Navarro-Alarcon

In this paper, we propose a novel formation controller for nonholonomic agents to form general parametric curves. First, we derive a unified parametric representation for both open and closed curves. Then, a leader-follower formation controller is designed to form the parametric curves. We consider directed communications and constant input disturbances rejection in the controller design. Rigorous Lyapunov-based stability analysis proves th... more
In this paper, we propose a novel formation controller for nonholonomic agents to form general parametric curves. First, we derive a unified parametric representation for both open and closed curves. Then, a leader-follower formation controller is designed to form the parametric curves. We consider directed communications and constant input disturbances rejection in the controller design. Rigorous Lyapunov-based stability analysis proves the asymptotic stability of the proposed controller. Detailed numerical simulations and experimental studies are conducted to verify the performance of the proposed method. less
Ride Acceptance Behaviour Investigation of Ride-sourcing Drivers Through
  Agent-based Simulation

By: Farnoud Ghasemi, Peyman Ashkrof, Rafal Kucharski

Ride-sourcing platforms such as Uber and Lyft offer drivers (i.e., platform suppliers) considerable freedom of choice in multiple aspects. At the operational level, drivers can freely accept or decline trip requests that can significantly impact system performance in terms of travellers' waiting time, drivers' idle time and income. Despite the extensive research into the supply-side operations, the behavioural aspects, particularly drivers'... more
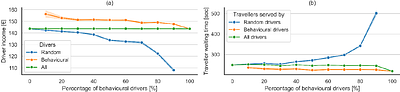
Ride-sourcing platforms such as Uber and Lyft offer drivers (i.e., platform suppliers) considerable freedom of choice in multiple aspects. At the operational level, drivers can freely accept or decline trip requests that can significantly impact system performance in terms of travellers' waiting time, drivers' idle time and income. Despite the extensive research into the supply-side operations, the behavioural aspects, particularly drivers' ride acceptance behaviour remains so far largely unknown. To this end, we reproduce the dynamics of a two-sided mobility platform on the road network of Delft using an agent-based simulator. Then, we implement a ride acceptance decision model enabling drivers to apply their acceptance strategies. Our findings reveal that drivers who follow the decision model, on average, earn higher income compared to drivers who randomly accept trip requests. The overall income equality between drivers with the acceptance decision is higher and travellers experience lower waiting time in this setting. less