Calibrate Once, Grow the Vocabulary: Candidate-Independent Scores for Conformal Risk Control in Open-Vocabulary Segmentation
Calibrate Once, Grow the Vocabulary: Candidate-Independent Scores for Conformal Risk Control in Open-Vocabulary Segmentation
Md Tanveer Hossain Munim, Bijoy Ahmed Saiem, Muhammad Abdullah Adnan
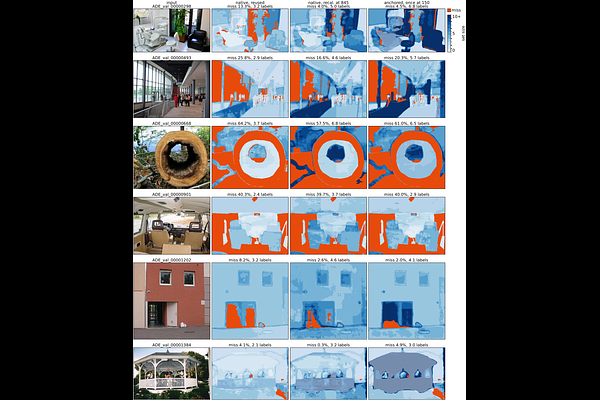
AbstractOpen-vocabulary segmenters accept class names at inference. Conformal risk control can bound how often their prediction sets miss the true label, but we show that this bound breaks when names are added after calibration. On ADE20K, a threshold calibrated for 10% risk at 150 names reaches up to 15.4% risk at 845 names in released CAT-Seg models. The risk exceeds the target on every calibration split, yet the prediction sets grow far less than the target requires. In SED they instead grow larger than needed. The cause is that pruning, cross-label attention and vocabulary normalisation make each label's score depend on the other requested labels. Scores can move either way, so a threshold recalibrated at a larger vocabulary need not hold at smaller ones. We remove this dependence without training by scoring each label against a fixed reference bank of names. A label's score then stays the same when names are added, so one calibration keeps its guarantee as the vocabulary grows. The guarantee holds whatever names are added, even ones chosen per image after seeing it. On three benchmarks and five segmenters, the converted models meet the target at every vocabulary size we evaluate. For CAT-Seg and SED at alpha=10%, they use at most one more label per pixel than the released models recalibrated at the grown vocabulary. Treating names instead of images as calibration samples also bounds the miss rate of added names. If the annotated names are a random sample of the names in the calibration images, an added name's expected miss rate on those images is at most the target. For harder added names, the excess is at most their gap in mean miss rate. Applied to Grounding DINO, which splits large vocabularies into chunks, the conversion also makes inference about six times faster.