Think Offline, Act in Real Time: Self-Improving Visual Game Agents through Code
Think Offline, Act in Real Time: Self-Improving Visual Game Agents through Code
Zipeng Qiu, Shusheng Xu, Jiale Li, Yukun Zhou, Chenyue Li, Wenshuang Li, Tongkai Yang, Binhang Yuan
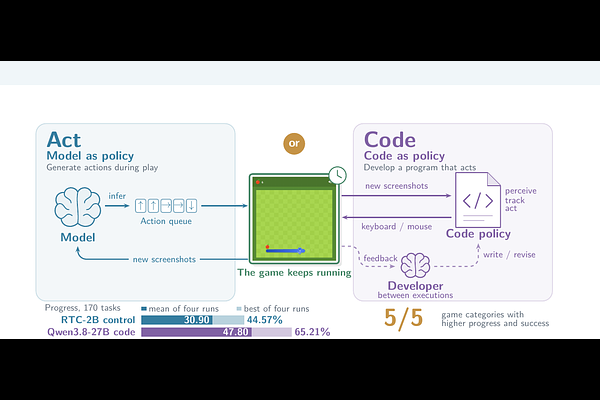
AbstractPre-trained models can read screens and reason about games, yet on an unfamiliar game, an agent still has to learn to play. We ask how an agent can self-improve on such a game from a few of its own attempts, in real-time visual games where the agent sees only the screen and the game keeps running while the agent thinks. We study two kinds of policy that can carry this improvement. In model as policy, a model selects actions during play; we adapt real-time chunking so that committed actions keep executing while the model reasons, and train a 2B controller for this interface. In code as policy, a model writes, tests, and revises a program between attempts, and the program acts during play. Across 170 GameWorld tasks, with at most eight one-minute executions per run, code as policy reaches 47.80% mean progress, against 30.90% for our trained controller, and leads in all five game categories. Improving the controller's weights on a single game, by contrast, yields only modest gains. These results favor letting a model think offline and storing what it learns in a program that acts in real time. Project repository: https://github.com/TabibitoQZP/SIGame