GEAR$^2$: Pruned Experts Live On through Gated Reuse of Activated Experts and a Missing-Mass Residual
GEAR$^2$: Pruned Experts Live On through Gated Reuse of Activated Experts and a Missing-Mass Residual
Linliang Chen, Yan Zhong, Wang Kang, Sai Li, Ji Wu, Ji Liu
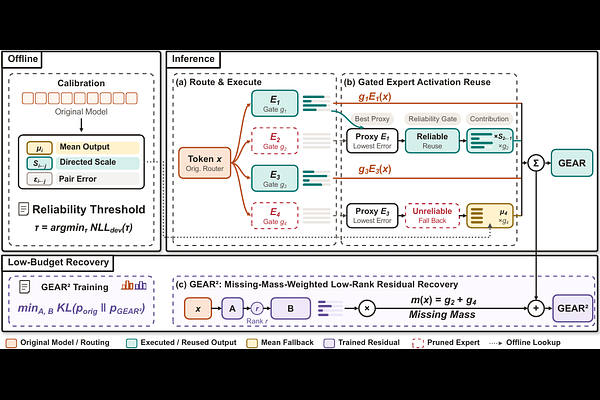
AbstractMixture-of-Experts (MoE) Large Language Models (LLMs) activate only a few experts per token while generally keeping all the experts in GPU memory for high efficiency. Expert pruning reduces this GPU memory footprint cost, yet discards the contribution of pruned experts. Existing remedies either rely on static substitutes, merge experts at the cost of altering their functions, or require costly recovery training. In this paper, we find that the functionalities of pruned experts can be efficiently reconstructed from the activated remaining experts. We propose GEAR (Gated Expert Activation Reuse), which reuses the scaled outputs of reliable activated experts without any training or additional expert computation. In addition, we propose GEAR$^2$ to further recover what reuse cannot express with an ultra-lightweight residual. On five MoE LLMs from 16B to 106B parameters with 25% and 50% of experts pruned, GEAR improves over its training-free counterparts in nearly every setting (up to 4 pp.) in terms of accuracy, and GEAR$^2$ outperforms baseline approaches (up to 2.75 pp.) in every setting on nine zero-shot benchmarks, with larger advantages (up to 2.72 pp. higher) under more aggressive pruning (up to 50%).